


Journal of Computer Applications ›› 2026, Vol. 46 ›› Issue (9): 2838-2846.DOI: 10.11772/j.issn.1001-9081.2025080969
• Data science and technology • Previous Articles
Zhenhui GONG1,2, Xiaoyu SHI1,2( ), Yun LU1,2, Yangcheng LIU3, Mingsheng SHANG1,2
Received:2025-08-26
Revised:2025-11-03
Accepted:2025-11-07
Online:2025-11-17
Published:2026-09-10
Contact:
Xiaoyu SHI
About author:GONG Zhenhui, born in 2000, M. S. candidate. His researchinterests include deep learning, reinforcement learning, recommender systems, group fairness.
龚镇辉1,2, 史晓雨1,2(), 鲁云1,2, 刘阳成3, 尚明生1,2
通讯作者:
史晓雨
作者简介:龚镇辉(2000—),男,福建漳州人,硕士研究生,主要研究方向:深度学习、强化学习、推荐系统、群体公平性基金资助:CLC Number:
Zhenhui GONG, Xiaoyu SHI, Yun LU, Yangcheng LIU, Mingsheng SHANG. Fair recommendation framework for large language models with sensitive attribute absence[J]. Journal of Computer Applications, 2026, 46(9): 2838-2846.
龚镇辉, 史晓雨, 鲁云, 刘阳成, 尚明生. 面向敏感属性缺失的大语言模型公平推荐框架[J]. 《计算机应用》唯一官方网站, 2026, 46(9): 2838-2846.
Add to citation manager EndNote|Ris|BibTeX
URL: https://www.joca.cn/EN/10.11772/j.issn.1001-9081.2025080969
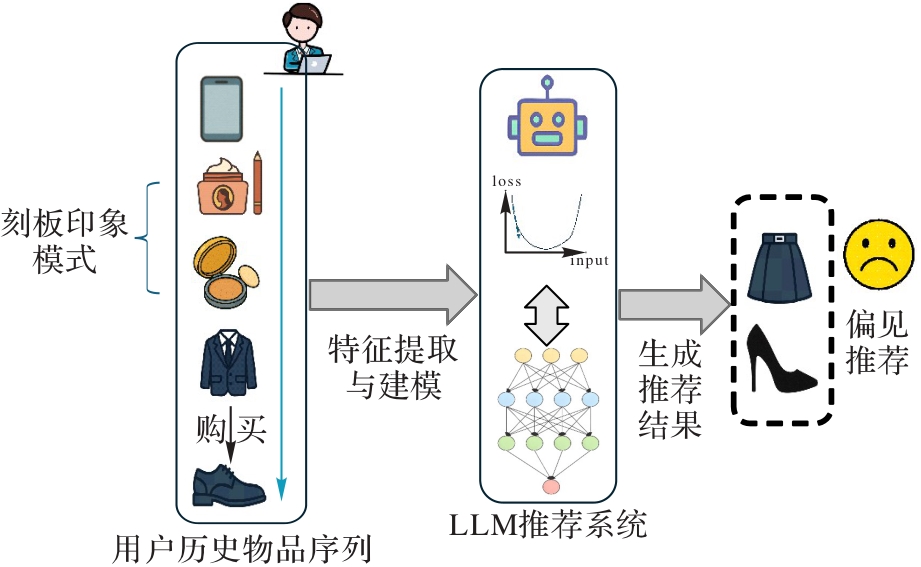
Fig. 1 Example of bias of user sensitive information
| 数据集 | 指标 | 男性用户 | 女性用户 |
|---|---|---|---|
| MovieLens-1M | NDCG@5 | 0.019 5 | 0.014 4 |
| Loss | 0.430 2 | 0.570 0 | |
| Max Grad | 0.644 5 | 0.822 2 | |
| LastFM-360K | NDCG@5 | 0.013 5 | 0.013 1 |
| Loss | 0.961 0 | 0.977 8 | |
| Max Grad | 0.771 2 | 0.807 8 |
Tab. 1 Comparison of BIGRec indicators on different datasets
| 数据集 | 指标 | 男性用户 | 女性用户 |
|---|---|---|---|
| MovieLens-1M | NDCG@5 | 0.019 5 | 0.014 4 |
| Loss | 0.430 2 | 0.570 0 | |
| Max Grad | 0.644 5 | 0.822 2 | |
| LastFM-360K | NDCG@5 | 0.013 5 | 0.013 1 |
| Loss | 0.961 0 | 0.977 8 | |
| Max Grad | 0.771 2 | 0.807 8 |
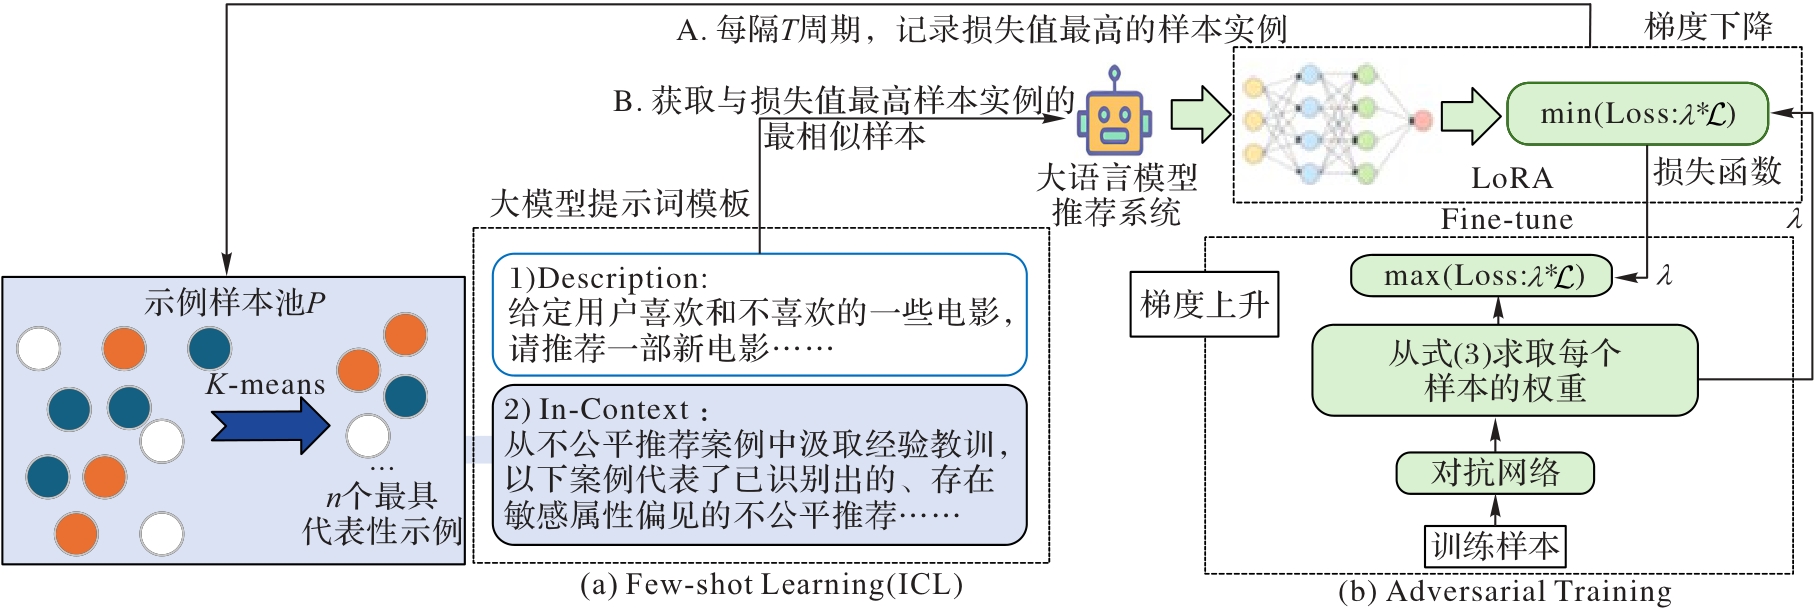
Fig. 2 Structure of FAIR-SAA
| 模型 | 基准 | k | ML-1M | ML-100K | LastFM-360K | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 性别 | 年龄 | 性别 | 年龄 | 性别 | 年龄 | |||||||||
| BIGRec | Naive | 3 | 0.004 2 | 0.006 3 | 0.003 0 | 0.005 4 | 0.006 6 | 0.004 3 | 0.002 5 | 0.002 8 | 0.000 4 | 0.000 2 | 0.014 4 | 0.013 9 |
| 10 | 0.005 8 | 0.010 5 | 0.003 9 | 0.007 3 | 0.008 0 | 0.007 7 | 0.001 8 | 0.001 2 | 0.000 4 | 0.002 1 | 0.014 0 | 0.012 1 | ||
| FAIR-SAA | 3 | 0.002 3 | 0.003 4 | 0.002 9 | 0.004 7 | 0.000 1 | 0.002 2 | 0.000 9 | 0.000 5 | 0.000 4 | 0.000 1 | 0.010 9 | 0.010 3 | |
| 10 | 0.002 6 | 0.004 0 | 0.005 7 | 0.011 7 | 0.000 3 | 0.001 6 | 0.001 7 | 0.002 4 | 0.000 6 | 0.002 1 | 0.009 2 | 0.005 4 | ||
| FACTER | 3 | 0.001 2 | 0.001 1 | 0.008 8 | 0.010 8 | 0.001 8 | 0.001 9 | 0.015 6 | 0.018 2 | 0.000 4 | 0.000 4 | 0.004 4 | 0.004 4 | |
| 10 | 0.000 1 | 0.003 1 | 0.005 3 | 0.000 1 | 0.004 0 | 0.008 4 | 0.016 1 | 0.019 4 | 0.003 0 | 0.007 6 | 0.001 3 | 0.010 1 | ||
| TALLRec | Naive | 3 | 0.001 1 | 0.001 9 | 0.006 1 | 0.007 8 | 0.002 2 | 0.004 0 | 0.012 2 | 0.014 5 | 0.004 1 | 0.003 3 | 0.019 4 | 0.018 4 |
| 10 | 0.004 0 | 0.009 4 | 0.008 4 | 0.014 6 | 0.000 9 | 0.004 9 | 0.010 1 | 0.009 2 | 0.004 0 | 0.003 1 | 0.020 2 | 0.020 2 | ||
| FAIR-SAA | 3 | 0.002 2 | 0.002 0 | 0.003 1 | 0.003 2 | 0.006 6 | 0.006 4 | 0.000 9 | 0.001 8 | 0.002 7 | 0.001 7 | 0.015 2 | 0.014 3 | |
| 10 | 0.002 2 | 0.001 8 | 0.002 7 | 0.001 8 | 0.004 4 | 0.000 6 | 0.000 9 | 0.002 6 | 0.003 1 | 0.002 5 | 0.015 0 | 0.013 1 | ||
| FACTER | 3 | 0.004 8 | 0.005 2 | 0.002 7 | 0.002 0 | 0.002 5 | 0.002 5 | 0.002 2 | 0.003 0 | 0.001 1 | 0.003 0 | 0.002 8 | 0.002 3 | |
| 10 | 0.006 2 | 0.009 4 | 0.006 9 | 0.015 1 | 0.004 8 | 0.009 8 | 0.004 7 | 0.009 9 | 0.001 0 | 0.002 6 | 0.001 3 | 0.002 1 | ||
| DRFO | 3 | 0.000 8 | 0.002 7 | 0.006 8 | 0.009 2 | 0.002 2 | 0.001 9 | 0.012 9 | 0.016 3 | 0.000 1 | 0.000 2 | 0.001 9 | 0.002 4 | |
| 10 | 0.004 0 | 0.006 7 | 0.006 9 | 0.009 1 | 0.005 7 | 0.017 7 | 0.019 6 | 0.035 5 | 0.000 1 | 0.000 2 | 0.003 0 | 0.005 8 | ||
Tab. 2 Experimental results of group fairness metrics
| 模型 | 基准 | k | ML-1M | ML-100K | LastFM-360K | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 性别 | 年龄 | 性别 | 年龄 | 性别 | 年龄 | |||||||||
| BIGRec | Naive | 3 | 0.004 2 | 0.006 3 | 0.003 0 | 0.005 4 | 0.006 6 | 0.004 3 | 0.002 5 | 0.002 8 | 0.000 4 | 0.000 2 | 0.014 4 | 0.013 9 |
| 10 | 0.005 8 | 0.010 5 | 0.003 9 | 0.007 3 | 0.008 0 | 0.007 7 | 0.001 8 | 0.001 2 | 0.000 4 | 0.002 1 | 0.014 0 | 0.012 1 | ||
| FAIR-SAA | 3 | 0.002 3 | 0.003 4 | 0.002 9 | 0.004 7 | 0.000 1 | 0.002 2 | 0.000 9 | 0.000 5 | 0.000 4 | 0.000 1 | 0.010 9 | 0.010 3 | |
| 10 | 0.002 6 | 0.004 0 | 0.005 7 | 0.011 7 | 0.000 3 | 0.001 6 | 0.001 7 | 0.002 4 | 0.000 6 | 0.002 1 | 0.009 2 | 0.005 4 | ||
| FACTER | 3 | 0.001 2 | 0.001 1 | 0.008 8 | 0.010 8 | 0.001 8 | 0.001 9 | 0.015 6 | 0.018 2 | 0.000 4 | 0.000 4 | 0.004 4 | 0.004 4 | |
| 10 | 0.000 1 | 0.003 1 | 0.005 3 | 0.000 1 | 0.004 0 | 0.008 4 | 0.016 1 | 0.019 4 | 0.003 0 | 0.007 6 | 0.001 3 | 0.010 1 | ||
| TALLRec | Naive | 3 | 0.001 1 | 0.001 9 | 0.006 1 | 0.007 8 | 0.002 2 | 0.004 0 | 0.012 2 | 0.014 5 | 0.004 1 | 0.003 3 | 0.019 4 | 0.018 4 |
| 10 | 0.004 0 | 0.009 4 | 0.008 4 | 0.014 6 | 0.000 9 | 0.004 9 | 0.010 1 | 0.009 2 | 0.004 0 | 0.003 1 | 0.020 2 | 0.020 2 | ||
| FAIR-SAA | 3 | 0.002 2 | 0.002 0 | 0.003 1 | 0.003 2 | 0.006 6 | 0.006 4 | 0.000 9 | 0.001 8 | 0.002 7 | 0.001 7 | 0.015 2 | 0.014 3 | |
| 10 | 0.002 2 | 0.001 8 | 0.002 7 | 0.001 8 | 0.004 4 | 0.000 6 | 0.000 9 | 0.002 6 | 0.003 1 | 0.002 5 | 0.015 0 | 0.013 1 | ||
| FACTER | 3 | 0.004 8 | 0.005 2 | 0.002 7 | 0.002 0 | 0.002 5 | 0.002 5 | 0.002 2 | 0.003 0 | 0.001 1 | 0.003 0 | 0.002 8 | 0.002 3 | |
| 10 | 0.006 2 | 0.009 4 | 0.006 9 | 0.015 1 | 0.004 8 | 0.009 8 | 0.004 7 | 0.009 9 | 0.001 0 | 0.002 6 | 0.001 3 | 0.002 1 | ||
| DRFO | 3 | 0.000 8 | 0.002 7 | 0.006 8 | 0.009 2 | 0.002 2 | 0.001 9 | 0.012 9 | 0.016 3 | 0.000 1 | 0.000 2 | 0.001 9 | 0.002 4 | |
| 10 | 0.004 0 | 0.006 7 | 0.006 9 | 0.009 1 | 0.005 7 | 0.017 7 | 0.019 6 | 0.035 5 | 0.000 1 | 0.000 2 | 0.003 0 | 0.005 8 | ||
| 模型 | 基准 | k | ML-1M | ML-100K | LastFM-360K | |||
|---|---|---|---|---|---|---|---|---|
| NDCG | HR | NDCG | HR | NDCG | HR | |||
| BIGRec | Naive | 3 | 0.014 9 | 0.017 6 | 0.015 8 | 0.020 0 | 0.013 2 | 0.013 8 |
| 10 | 0.020 5 | 0.033 4 | 0.023 7 | 0.042 4 | 0.014 4 | 0.017 4 | ||
| FAIR-SAA | 3 | 0.016 3 | 0.019 0 | 0.015 4 | 0.020 0 | 0.012 4 | 0.013 0 | |
| 10 | 0.023 0 | 0.037 8 | 0.022 9 | 0.041 2 | 0.014 0 | 0.017 4 | ||
| FACTER | 3 | 0.018 6 | 0.022 7 | 0.013 7 | 0.018 1 | 0.007 7 | 0.008 7 | |
| 10 | 0.024 6 | 0.039 3 | 0.018 9 | 0.033 4 | 0.001 0 | 0.015 1 | ||
| TALLRec | Naive | 3 | 0.011 9 | 0.013 8 | 0.014 2 | 0.018 1 | 0.012 9 | 0.013 8 |
| 10 | 0.018 0 | 0.030 6 | 0.022 3 | 0.041 2 | 0.014 4 | 0.018 2 | ||
| FAIR-SAA | 3 | 0.011 3 | 0.013 0 | 0.015 2 | 0.018 5 | 0.012 6 | 0.013 4 | |
| 10 | 0.015 5 | 0.025 2 | 0.023 2 | 0.041 2 | 0.014 4 | 0.018 6 | ||
| FACTER | 3 | 0.014 8 | 0.017 1 | 0.009 7 | 0.012 3 | 0.007 9 | 0.008 7 | |
| 10 | 0.022 8 | 0.040 3 | 0.015 4 | 0.028 1 | 0.009 3 | 0.012 8 | ||
| DRFO | 3 | 0.013 7 | 0.018 6 | 0.018 7 | 0.024 4 | 0.006 9 | 0.009 3 | |
| 10 | 0.020 9 | 0.038 8 | 0.031 9 | 0.060 6 | 0.012 3 | 0.024 9 | ||
Tab. 3 Experimental results of recommendation performance metrics
| 模型 | 基准 | k | ML-1M | ML-100K | LastFM-360K | |||
|---|---|---|---|---|---|---|---|---|
| NDCG | HR | NDCG | HR | NDCG | HR | |||
| BIGRec | Naive | 3 | 0.014 9 | 0.017 6 | 0.015 8 | 0.020 0 | 0.013 2 | 0.013 8 |
| 10 | 0.020 5 | 0.033 4 | 0.023 7 | 0.042 4 | 0.014 4 | 0.017 4 | ||
| FAIR-SAA | 3 | 0.016 3 | 0.019 0 | 0.015 4 | 0.020 0 | 0.012 4 | 0.013 0 | |
| 10 | 0.023 0 | 0.037 8 | 0.022 9 | 0.041 2 | 0.014 0 | 0.017 4 | ||
| FACTER | 3 | 0.018 6 | 0.022 7 | 0.013 7 | 0.018 1 | 0.007 7 | 0.008 7 | |
| 10 | 0.024 6 | 0.039 3 | 0.018 9 | 0.033 4 | 0.001 0 | 0.015 1 | ||
| TALLRec | Naive | 3 | 0.011 9 | 0.013 8 | 0.014 2 | 0.018 1 | 0.012 9 | 0.013 8 |
| 10 | 0.018 0 | 0.030 6 | 0.022 3 | 0.041 2 | 0.014 4 | 0.018 2 | ||
| FAIR-SAA | 3 | 0.011 3 | 0.013 0 | 0.015 2 | 0.018 5 | 0.012 6 | 0.013 4 | |
| 10 | 0.015 5 | 0.025 2 | 0.023 2 | 0.041 2 | 0.014 4 | 0.018 6 | ||
| FACTER | 3 | 0.014 8 | 0.017 1 | 0.009 7 | 0.012 3 | 0.007 9 | 0.008 7 | |
| 10 | 0.022 8 | 0.040 3 | 0.015 4 | 0.028 1 | 0.009 3 | 0.012 8 | ||
| DRFO | 3 | 0.013 7 | 0.018 6 | 0.018 7 | 0.024 4 | 0.006 9 | 0.009 3 | |
| 10 | 0.020 9 | 0.038 8 | 0.031 9 | 0.060 6 | 0.012 3 | 0.024 9 | ||
| 模型 | k | ML-1M | LastFM-360K | ||||||
|---|---|---|---|---|---|---|---|---|---|
| NDCG | HR | NDCG | HR | ||||||
| FAIR-SAA(完整模型) | 10 | 0.002 6 | 0.004 0 | 0.023 0 | 0.037 8 | 0.000 6 | 0.002 1 | 0.014 0 | 0.017 4 |
| 自适应提示 | 10 | 0.004 9 | 0.006 4 | 0.022 2 | 0.035 6 | 0.002 5 | 0.001 7 | 0.011 1 | 0.013 4 |
| 对抗重加权学习 | 10 | 0.003 7 | 0.004 5 | 0.020 9 | 0.032 8 | 0.001 5 | 0.002 5 | 0.012 0 | 0.015 0 |
Tab. 4 Ablation study results
| 模型 | k | ML-1M | LastFM-360K | ||||||
|---|---|---|---|---|---|---|---|---|---|
| NDCG | HR | NDCG | HR | ||||||
| FAIR-SAA(完整模型) | 10 | 0.002 6 | 0.004 0 | 0.023 0 | 0.037 8 | 0.000 6 | 0.002 1 | 0.014 0 | 0.017 4 |
| 自适应提示 | 10 | 0.004 9 | 0.006 4 | 0.022 2 | 0.035 6 | 0.002 5 | 0.001 7 | 0.011 1 | 0.013 4 |
| 对抗重加权学习 | 10 | 0.003 7 | 0.004 5 | 0.020 9 | 0.032 8 | 0.001 5 | 0.002 5 | 0.012 0 | 0.015 0 |
| m | NDCG@10 | HR@10 | 性别 | 年龄 | ||
|---|---|---|---|---|---|---|
| 1 | 0.021 2 | 0.034 4 | 0.004 5 | 0.007 0 | 0.005 0 | 0.009 8 |
| 2 | 0.024 6 | 0.039 6 | 0.008 6 | 0.012 9 | 0.005 8 | 0.010 4 |
| 4 | 0.022 9 | 0.036 4 | 0.005 1 | 0.005 2 | 0.006 0 | 0.014 8 |
| 6 | 0.022 0 | 0.035 6 | 0.006 6 | 0.006 4 | 0.009 5 | 0.016 2 |
| 8 | 0.023 0 | 0.037 8 | 0.002 6 | 0.004 0 | 0.005 8 | 0.011 7 |
| 16 | 0.022 9 | 0.037 0 | 0.005 6 | 0.007 0 | 0.006 9 | 0.013 1 |
Tab. 5 Impact of number of contextual instance samples on performance
| m | NDCG@10 | HR@10 | 性别 | 年龄 | ||
|---|---|---|---|---|---|---|
| 1 | 0.021 2 | 0.034 4 | 0.004 5 | 0.007 0 | 0.005 0 | 0.009 8 |
| 2 | 0.024 6 | 0.039 6 | 0.008 6 | 0.012 9 | 0.005 8 | 0.010 4 |
| 4 | 0.022 9 | 0.036 4 | 0.005 1 | 0.005 2 | 0.006 0 | 0.014 8 |
| 6 | 0.022 0 | 0.035 6 | 0.006 6 | 0.006 4 | 0.009 5 | 0.016 2 |
| 8 | 0.023 0 | 0.037 8 | 0.002 6 | 0.004 0 | 0.005 8 | 0.011 7 |
| 16 | 0.022 9 | 0.037 0 | 0.005 6 | 0.007 0 | 0.006 9 | 0.013 1 |
| K | NDCG@10 | HR@10 | 性别 | 年龄 | ||
|---|---|---|---|---|---|---|
| 2 | 0.017 2 | 0.029 4 | 0.007 5 | 0.006 4 | 0.003 8 | 0.006 8 |
| 4 | 0.020 4 | 0.033 4 | 0.004 7 | 0.008 0 | 0.000 1 | 0.001 0 |
| 8 | 0.023 0 | 0.037 8 | 0.002 6 | 0.004 0 | 0.005 8 | 0.011 7 |
| 16 | 0.017 9 | 0.029 2 | 0.009 4 | 0.010 0 | 0.001 0 | 0.006 5 |
Tab. 6 Impact of cluster count on performance
| K | NDCG@10 | HR@10 | 性别 | 年龄 | ||
|---|---|---|---|---|---|---|
| 2 | 0.017 2 | 0.029 4 | 0.007 5 | 0.006 4 | 0.003 8 | 0.006 8 |
| 4 | 0.020 4 | 0.033 4 | 0.004 7 | 0.008 0 | 0.000 1 | 0.001 0 |
| 8 | 0.023 0 | 0.037 8 | 0.002 6 | 0.004 0 | 0.005 8 | 0.011 7 |
| 16 | 0.017 9 | 0.029 2 | 0.009 4 | 0.010 0 | 0.001 0 | 0.006 5 |
| 类别 | 电影名称 |
|---|---|
| 真实交互 | The Princess Bride (1987) |
| 高分偏好 | The Forrest Gump (1994);The Casablanca (1942) |
| 低分记录 | The Caligula (1980); The Halloween 4: The Return of Michael Myers (1988) |
Tab. 7 User profile and actual interactions of User_ID 6021
| 类别 | 电影名称 |
|---|---|
| 真实交互 | The Princess Bride (1987) |
| 高分偏好 | The Forrest Gump (1994);The Casablanca (1942) |
| 低分记录 | The Caligula (1980); The Halloween 4: The Return of Michael Myers (1988) |
| 排名 | 模型 | 推荐电影 | 类型 |
|---|---|---|---|
| 1 | BIGRec | The Bridge on the River Kwai (1957) | Drama, War |
| FAIR-SAA | The Godfather (1972) | Action, Crime, Drama | |
| 2 | BIGRec | The Bridge at Remagen (1969) | Action, War |
| FAIR-SAA | The Princess Bride (1987) | Action, Adventure, Comedy, Romance | |
| 3 | BIGRec | The Band Wagon (1953) | Comedy, Musical |
| FAIR-SAA | The Big Lebowski (1998) | Comedy, Crime | |
| 4 | BIGRec | The Great Escape (1963) | Adventure, War |
| FAIR-SAA | The Towering Inferno (1974) | Action, Drama |
Tab. 8 Comparison of recommendation lists from different models for User_ID 6021
| 排名 | 模型 | 推荐电影 | 类型 |
|---|---|---|---|
| 1 | BIGRec | The Bridge on the River Kwai (1957) | Drama, War |
| FAIR-SAA | The Godfather (1972) | Action, Crime, Drama | |
| 2 | BIGRec | The Bridge at Remagen (1969) | Action, War |
| FAIR-SAA | The Princess Bride (1987) | Action, Adventure, Comedy, Romance | |
| 3 | BIGRec | The Band Wagon (1953) | Comedy, Musical |
| FAIR-SAA | The Big Lebowski (1998) | Comedy, Crime | |
| 4 | BIGRec | The Great Escape (1963) | Adventure, War |
| FAIR-SAA | The Towering Inferno (1974) | Action, Drama |
| [1] | Gao Y, Sheng T, Xiang Y, et al. Chat-REC: towards interactive and explainable LLMs-augmented recommender system[PP/OL]. V2. arXiv (2023-04-04) [2024-08-01].. |
| [2] | Li Y, Ge Y, Zhang Y. Tutorial on fairness of machine learning in recommender systems [C]// SIGIR 2021. New York: ACM, 2021: 2654-2657. |
| [3] | Zhang J, Bao K, Zhang Y, et al. Is ChatGPT fair for recommendation? evaluating fairness in large language model recommendation [C]// RecSys 2023. New York: ACM, 2023: 993-999. |
| [4] | Deldjoo Y, Nazary F. A normative framework for benchmarking consumer fairness in large language model recommender system [PP/OL]. V2. arXiv (2024-09-11) [2025-09-03]. . |
| [5] | Zhao Z, Fan W, Li J, et al. Recommender systems in the era of Large Language Models (LLMs) [J]. IEEE Transactions on Knowledge and Data Engineering, 2024, 36(11): 6889-6907. |
| [6] | Li Y, Du M, Song R, et al. A survey on fairness in large language models[PP/OL]. V2. arXiv (2024-02-21) [2024-09-03].. |
| [7] | Ren W, Wang L, Liu K, et al. Mitigating popularity bias in recommendation with unbalanced interactions: a gradient perspective [C]// ICDM 2022. Piscataway: IEEE, 2022: 438-447. |
| [8] | Brown A, Tomasev N, Freyberg J, et al. Detecting shortcut learning for fair medical AI using shortcut testing [J]. Nature Communications, 2023, 14: No.4314. |
| [9] | Erion G, Janizek J D, Sturmfels P, et al. Improving performance of deep learning models with axiomatic attribution priors and expected gradients[J]. Nature Machine Intelligence, 2021, 3(7): 620-631. |
| [10] | Sundararajan M, Taly A, Yan Q. Axiomatic attribution for deep networks [J]. Journal of Machine Learning Research, 2017, 70: 3319-3328. |
| [11] | Zeng H, He Z, Yue Z, et al. Fair sequential recommendation without user demographics [C]// SIGIR 2024. New York: ACM, 2024: 395-404. |
| [12] | Bao K, Zhang J, Wang W, et al. A bi-step grounding paradigm for large language models in recommendation systems [J]. ACM Transactions on Recommender Systems, 2025, 3(4): No.53. |
| [13] | Shi X, Liu Q, Xie H, et al. Relieving popularity bias in interactive recommendation: a diversity-novelty-aware reinforcement learning approach [J]. ACM Transactions on Information Systems, 2024, 42(2): No.52. |
| [14] | Shi T, Zhang Y, Zhang J, et al. Fair recommendations with limited sensitive attributes: a distributionally robust optimization approach [C]// SIGIR 2024. New York: ACM, 2024: 448-457. |
| [15] | Li Y, Chen H, Fu Z, et al. User-oriented fairness in recommendation [C]// WWW 2021. New York: ACM, 2021: 624-632. |
| [16] | 李家宁,熊睿彬,兰艳艳,等. 因果机器学习的前沿进展综述[J]. 计算机研究与发展, 2023, 60(1): 59-84. |
| Li Jianing, Xiong Ruibin, Lan Yanyan, et al. Overview of the frontier progress of causal machine learning [J]. Journal of Computer Research and Development, 2023, 60(1): 59-84. | |
| [17] | Beutel A, Chen J, Doshi T, et al. Fairness in recommendation ranking through pairwise comparisons [C]// KDD 2019. New York: ACM, 2019: 2212-2220. |
| [18] | Hua W, Ge Y, Xu S, et al. UP5: unbiased foundation model for fairness-aware recommendation [C]// EACL (Volume 1: Long Papers) 2024. Stroudsburg: ACL, 2024: 1899-1912. |
| [19] | Fayyazi A, Kamal M, Pedram M. FACTER: fairness-aware conformal thresholding and prompt engineering for enabling fair LLM-based recommender systems [J]. Journal of Machine Learning Research, 2025, 267: 16407-16422. |
| [20] | 闫萌,徐偲,黄海槟,等. 基于大语言模型的可信多模态推荐算法[J]. 计算机研究与发展, 2025, 62(7): 1611-1621. |
| Yan Meng, Xu Cai, Huang Haibin, et al. Large language model-based trusted multi-modal recommendation algorithm[J]. Journal of Computer Research and Development, 2025, 62(7): 1611-1621. | |
| [21] | 高云帆,郁董卿,王思琪,等.大语言模型驱动的选址推荐系统[J]. 计算机研究与发展, 2024, 61(7): 1681-1696. |
| Gao Yunfan, Yu Dongqing, Wang Siqi, et al. Large language model powered site selection recommender system [J]. Journal of Computer Research and Development, 2024, 61(7): 1681-1696. | |
| [22] | Zhu X, Wang Y, Gao H, et al. Recommender systems meet large language model agents: a survey [J]. Foundations and Trends® in Privacy and Security, 2025, 7(4): 247-396. |
| [23] | Zhang C, Chen S, Zhang X, et al. Reinforcing long-term performance in recommender systems with user-oriented exploration policy [C]// SIGIR 2024. New York: ACM, 2024: 1850-1860. |
| [24] | Bao K, Zhang J, Zhang Y, et al. TALLRec: an effective and efficient tuning framework to align large language model with recommendation [C]// RecSys 2023. New York: ACM, 2023: 1007-1014. |
| [25] | Lahoti P, Beutel A, Chen J, et al. Fairness without demographics through adversarially reweighted learning [C]// NeurIPS 2020. Red Hook: Curran Associates Inc., 2020: 728-740. |
| [26] | Wu Y, Xie R, Zhu Y, et al. Selective fairness in recommendation via prompts [C]// SIGIR 2022. New York: ACM, 2022: 2657-2662. |
| [27] | Harper F M, Konstan J A. The MovieLens datasets: history and context [J]. ACM Transactions on Interactive Intelligent Systems, 2015, 5(4): No.19. |
| [28] | Music Technology Group, Universitat Pompeu Fabra. Last.fm dataset 360K [DS/OL]. (2010-03) [2025-01-23].. |
| [29] | Wei T, He J. Comprehensive fair meta-learned recommender system [C]// KDD 2022. New York: ACM, 2022: 1989-1999. |
| [1] | Yaoran HUO, Huizhi LI, Dahe ZENG, Zhenyu TANG, Chenmei LIU, Yan WU, Xiao ZHANG, Siqin CHEN, Houhui YANG. Contract review framework based on dynamic rule generation and neuro-symbolic reasoning using large language models [J]. Journal of Computer Applications, 2026, 46(9): 2820-2826. |
| [2] | Xinliang LIU, Yushi XU, Dubai LI, Yanzhao REN. Survey of knowledge graph-based question answering methods [J]. Journal of Computer Applications, 2026, 46(8): 2394-2410. |
| [3] | Yue ZHANG, Yuhan GUO. Ride-hailing spatio-temporal demand forecasting method via large language model-driven semantic quantification [J]. Journal of Computer Applications, 2026, 46(8): 2467-2476. |
| [4] | Mengting WANG, Shuanliang GAO, Wenrui LIAO, Geng LI, Jiaxing ZHANG, Yuanfang ZHU, Tiange ZHAO, Yonghui LIU, Hongru LIANG. Message consistency parsing framework for aviation domain [J]. Journal of Computer Applications, 2026, 46(8): 2681-2690. |
| [5] | Yadian CHENG, Yingying LI, Ping ZHANG, Fangbing QIU, Xiaonan CHAI, Yuqiao SHU. Dual-role interaction mechanism-based large language model for psychological health [J]. Journal of Computer Applications, 2026, 46(7): 2054-2063. |
| [6] | Linkai ZHU, Lu YANG, Hongjie ZHANG, Zijin WU, Lu LIU. Smart contract generation framework driven by LLM and SWRL for cross-border data compliance across heterogeneous blockchains [J]. Journal of Computer Applications, 2026, 46(7): 2074-2084. |
| [7] | Jiahang LI, Qilong HAN, Lijie LI, Hui ZHANG. Large language model-driven method for qualifier enhancement in hyper-relational knowledge graphs [J]. Journal of Computer Applications, 2026, 46(7): 2043-2053. |
| [8] | Didi HOU, Shaodong HONG, Yujie FU, Yunhe CUI, Guowei SHEN. Cybersecurity named entity recognition method based on large language model linking [J]. Journal of Computer Applications, 2026, 46(7): 2064-2073. |
| [9] | Yuqi WANG, Yangsen ZHANG, Pu WANG. High school English reading comprehension model integrating knowledge augmentation and contrastive learning [J]. Journal of Computer Applications, 2026, 46(7): 2096-2103. |
| [10] | Yuan GAO, Xuebin CHEN, Liu WANG, Kaiguang MA. Distributed graph publishing method based on dual-granularity privacy protection [J]. Journal of Computer Applications, 2026, 46(7): 2164-2173. |
| [11] | Yusheng YI, Zhaohao HUANG, Zihao DENG, Leilei KONG, Haoliang QI. CORER: collaborative multi-knowledge large language model prompt framework for IT application innovation database migration [J]. Journal of Computer Applications, 2026, 46(6): 1811-1817. |
| [12] | Taixin CAI, Fengfeng WEI. Large language model-enhanced ant colony optimization for multi-solution traveling salesman problems [J]. Journal of Computer Applications, 2026, 46(6): 1712-1720. |
| [13] | Jintao WANG, Zhilin GAO, Qixiang MENG, Fanliang BU. Legal case retrieval method via case information reformulation using large language model [J]. Journal of Computer Applications, 2026, 46(6): 1785-1792. |
| [14] | Longyu XIONG, Shengdong DU, Haochen SHI, Jie HU, Yan YANG, Tianrui LI. Government affairs hotline question answering system based on knowledge-enhanced large language model architecture [J]. Journal of Computer Applications, 2026, 46(6): 1721-1727. |
| [15] | Qianfei WANG, Yang LI, Deyu LI, Suge WANG. Dual-channel feature fusion representation method for short-text clustering based on large language model [J]. Journal of Computer Applications, 2026, 46(5): 1441-1449. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||
