


Journal of Computer Applications ›› 2026, Vol. 46 ›› Issue (9): 2948-2958.DOI: 10.11772/j.issn.1001-9081.2025080987
• Computer software technology • Previous Articles
Yun BIAN1,2, Haiquan WANG1,2, Yi CHEN1,2, Zhe CUI1,2( )
Received:2025-08-27
Revised:2025-11-04
Accepted:2025-11-07
Online:2025-11-17
Published:2026-09-10
Contact:
Zhe CUI
About author:BIAN Yun, born in 1988, Ph. D. candidate, senior engineer. Her research interests include natural language processing, large language models.Supported by:
边赟1,2, 王海全1,2, 陈义1,2, 崔喆1,2()
通讯作者:
崔喆
作者简介:边赟(1988—),女,甘肃酒泉人,高级工程师,博士研究生,主要研究方向:自然语言处理、大语言模型基金资助:CLC Number:
Yun BIAN, Haiquan WANG, Yi CHEN, Zhe CUI. Construction method of software defect prediction dataset with explainability[J]. Journal of Computer Applications, 2026, 46(9): 2948-2958.
边赟, 王海全, 陈义, 崔喆. 具备可解释性的软件缺陷预测数据集构建方法[J]. 《计算机应用》唯一官方网站, 2026, 46(9): 2948-2958.
Add to citation manager EndNote|Ris|BibTeX
URL: https://www.joca.cn/EN/10.11772/j.issn.1001-9081.2025080987
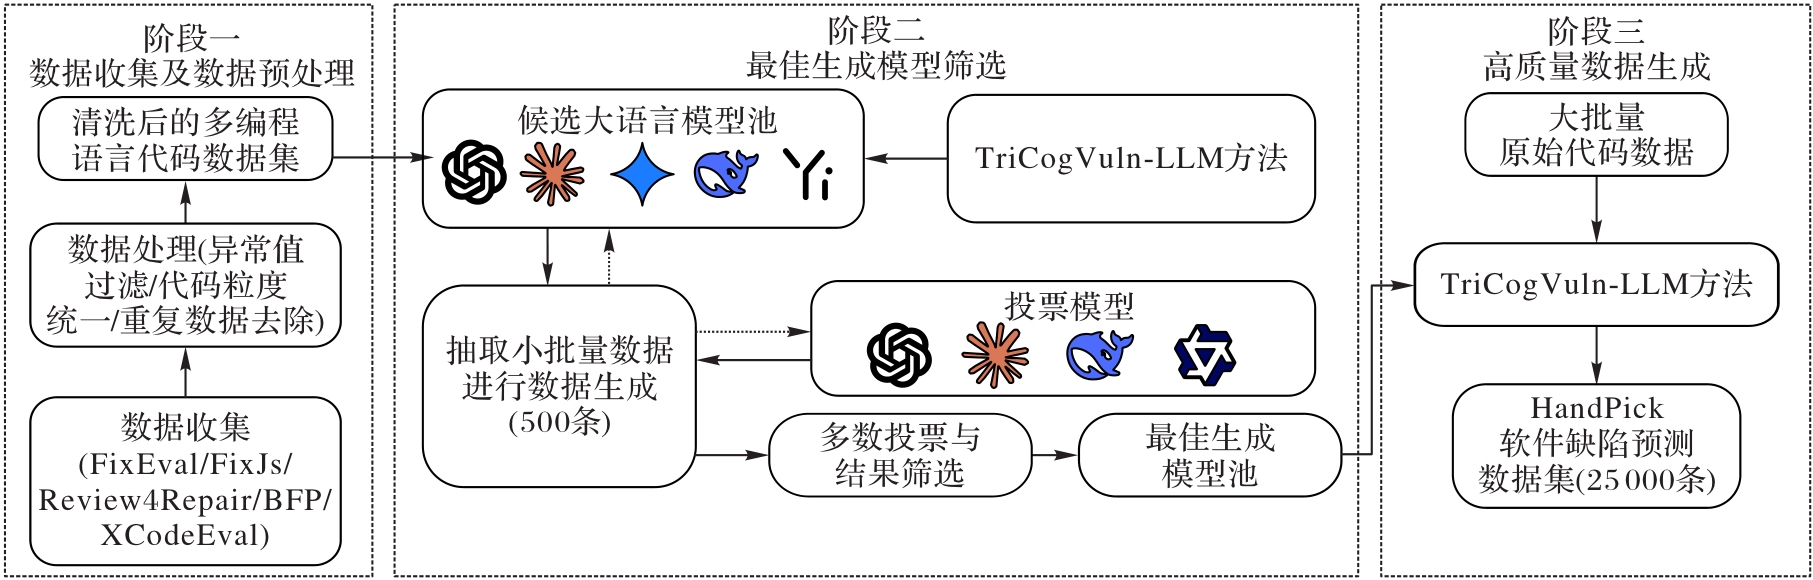
Fig. 1 Flow of dataset construction method
编程 语言类型 | 数据集名称 | 数据量 | 原任务类型 |
|---|---|---|---|
| Java | FixEval[ | 43 000 | BugFix |
| Review4Repair[ | 59 172 | BugFix | |
| BFP[ | 1 190 331 | Program Repair | |
| XCodeEval[ | 574 448 | Program Repair | |
| C/C++ | XCodeEval[ | 3 409 220 | Program Repair |
| Python | XCodeEval[ | 461 356 | Program Repair |
| JavaScript | FixJS[ | 55 551 | BugFix |
Tab. 1 Information of collected datasets
编程 语言类型 | 数据集名称 | 数据量 | 原任务类型 |
|---|---|---|---|
| Java | FixEval[ | 43 000 | BugFix |
| Review4Repair[ | 59 172 | BugFix | |
| BFP[ | 1 190 331 | Program Repair | |
| XCodeEval[ | 574 448 | Program Repair | |
| C/C++ | XCodeEval[ | 3 409 220 | Program Repair |
| Python | XCodeEval[ | 461 356 | Program Repair |
| JavaScript | FixJS[ | 55 551 | BugFix |
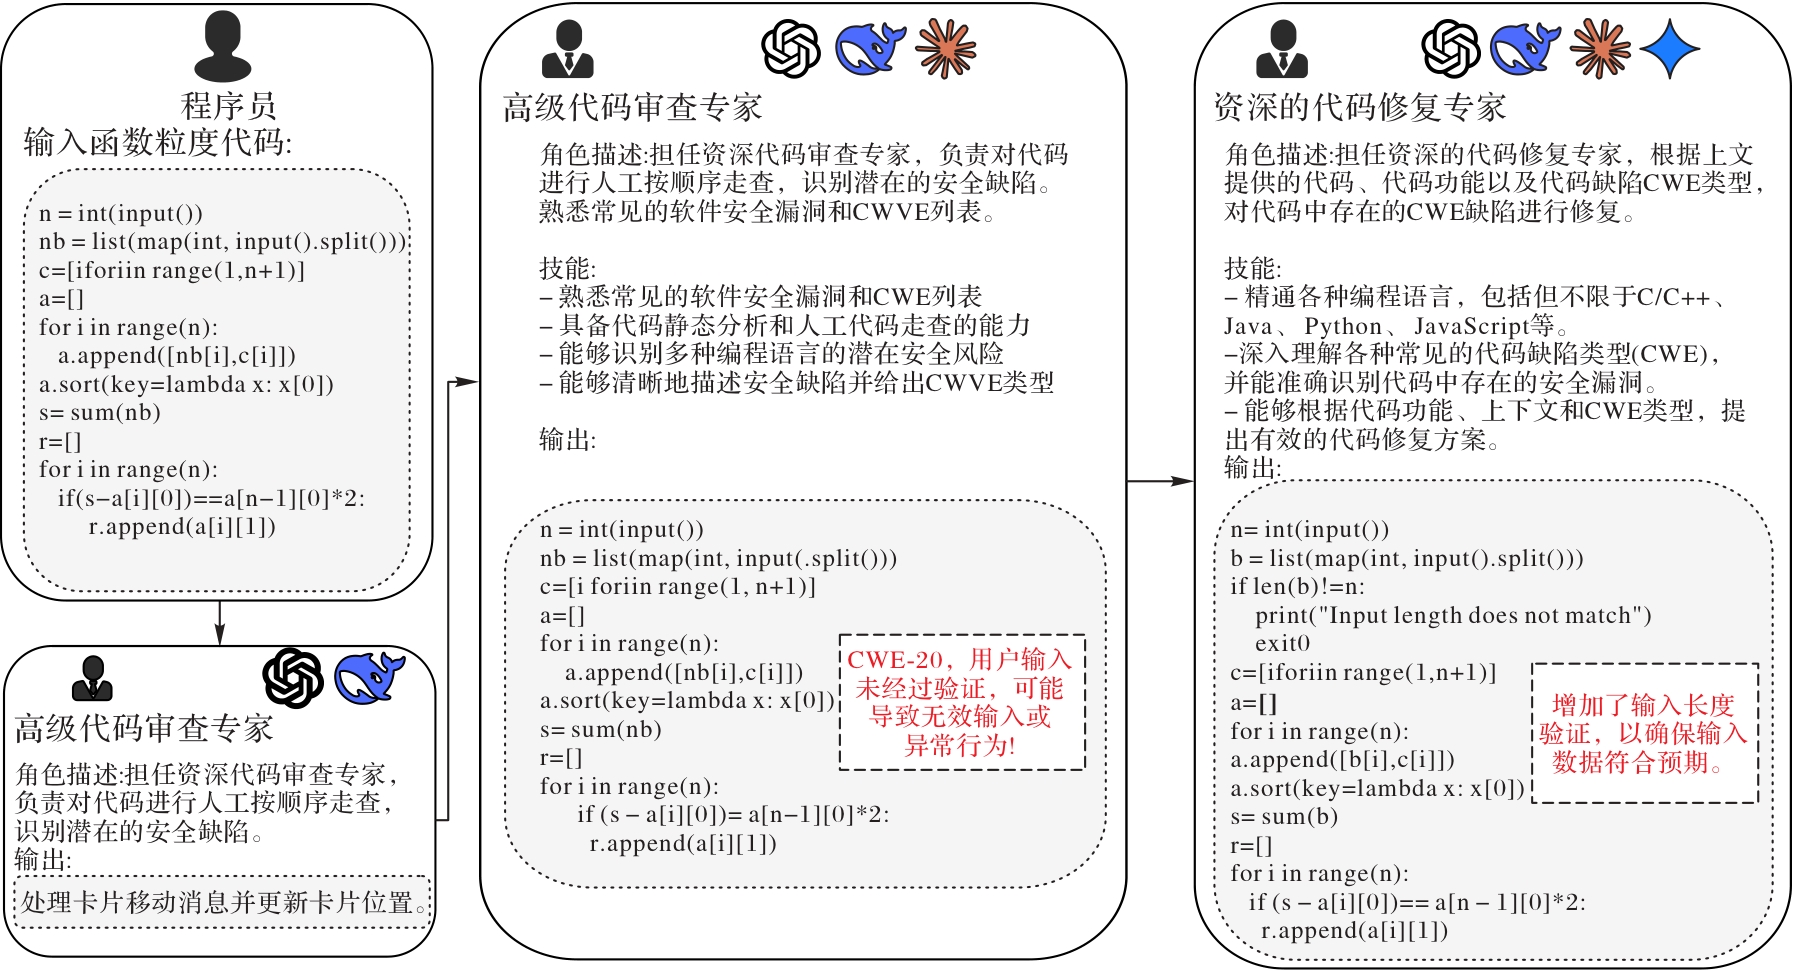
Fig. 2 Workflow of TriCogVuln-LLM method
| 编号 | CWE ID | CWE描述 | 不同年份的排名 | |||||
|---|---|---|---|---|---|---|---|---|
| 2019 | 2020 | 2021 | 2022 | 2023 | 2024 | |||
| 1 | CWE-787 | 越界写入 | 12 | 2 | 1 | 1 | 1 | 2 |
| 2 | CWE-79 | Web页面生成时对输入的转义处理不恰当 | 2 | 1 | 2 | 2 | 2 | 1 |
| 3 | CWE-89 | SQL注入问题 | 6 | 6 | 6 | 3 | 3 | 3 |
| 4 | CWE-416 | 内存不安全,释放后使用 | 7 | 8 | 7 | 7 | 4 | 8 |
| 5 | CWE-78 | OS命令注入 | 11 | 10 | 5 | 6 | 5 | 7 |
| 6 | CWE-20 | 用户输入未经过验证 | 3 | 3 | 4 | 4 | 6 | 12 |
| 7 | CWE-125 | 越界读取 | 5 | 4 | 3 | 5 | 7 | 6 |
| 8 | CWE-22 | 文件处理;对路径名的限制不恰当 | 10 | 12 | 8 | 8 | 8 | 5 |
| 9 | CWE-352 | 数据真实性验证不足;跨站请求伪造 | 9 | 9 | 9 | 9 | 9 | 4 |
| 10 | CWE-434 | 危险类型文件的不加限制上传 | 16 | 15 | 10 | 10 | 10 | 10 |
Tab. 2 CWE-TOP 10 ranking
| 编号 | CWE ID | CWE描述 | 不同年份的排名 | |||||
|---|---|---|---|---|---|---|---|---|
| 2019 | 2020 | 2021 | 2022 | 2023 | 2024 | |||
| 1 | CWE-787 | 越界写入 | 12 | 2 | 1 | 1 | 1 | 2 |
| 2 | CWE-79 | Web页面生成时对输入的转义处理不恰当 | 2 | 1 | 2 | 2 | 2 | 1 |
| 3 | CWE-89 | SQL注入问题 | 6 | 6 | 6 | 3 | 3 | 3 |
| 4 | CWE-416 | 内存不安全,释放后使用 | 7 | 8 | 7 | 7 | 4 | 8 |
| 5 | CWE-78 | OS命令注入 | 11 | 10 | 5 | 6 | 5 | 7 |
| 6 | CWE-20 | 用户输入未经过验证 | 3 | 3 | 4 | 4 | 6 | 12 |
| 7 | CWE-125 | 越界读取 | 5 | 4 | 3 | 5 | 7 | 6 |
| 8 | CWE-22 | 文件处理;对路径名的限制不恰当 | 10 | 12 | 8 | 8 | 8 | 5 |
| 9 | CWE-352 | 数据真实性验证不足;跨站请求伪造 | 9 | 9 | 9 | 9 | 9 | 4 |
| 10 | CWE-434 | 危险类型文件的不加限制上传 | 16 | 15 | 10 | 10 | 10 | 10 |
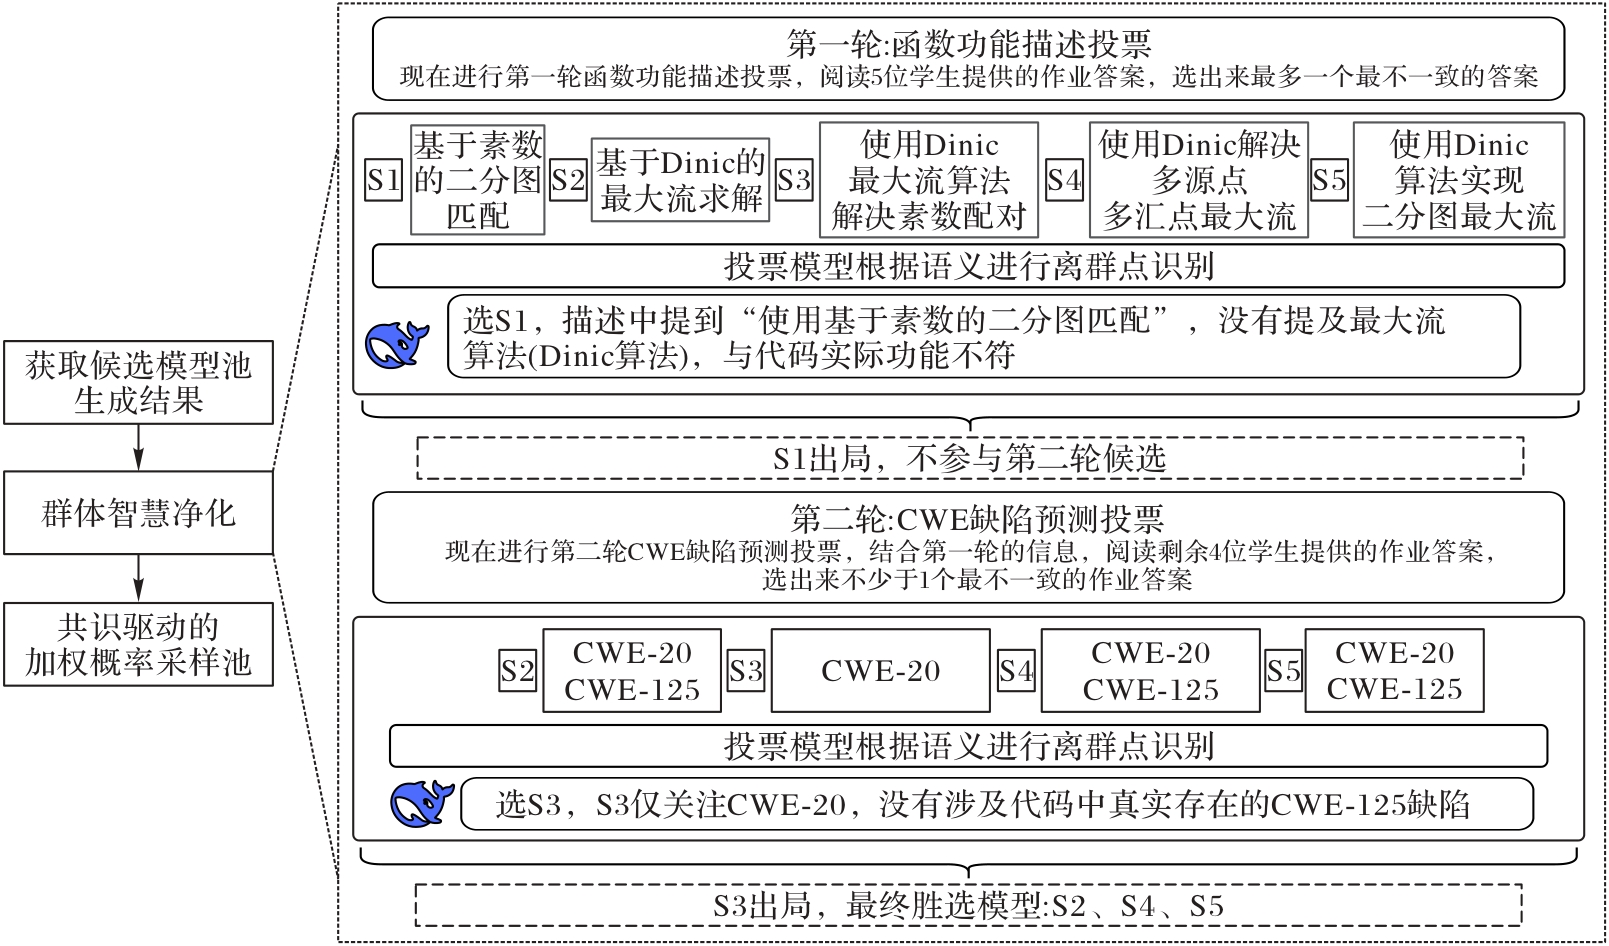
Fig. 3 Schematic diagram of consensus voting mechanism
| 模型 | 模型类别 | 调用方式 | 参数量/109 |
|---|---|---|---|
| GPT-4o | 闭源模型 | API调用 | — |
| Gemini-1.5-pro | 闭源模型 | API调用 | — |
| Claude-3.5-Sonnet | 闭源模型 | API调用 | — |
| Qwen2.5-14B-Instruct | 开源模型 | API调用 | 14 |
| Qwen2.5-14B-CodeXGLUE | 微调模型 | API调用 | 14 |
| Qwen2.5-14B-Draper VDISC | 微调模型 | API调用 | 14 |
| Qwen2.5-14B-ReposVul | 微调模型 | API调用 | 14 |
| DeepSeek-V3 | 开源模型 | API调用 | 671 |
| Qwen2.5-72B-Instruct | 开源模型 | API调用 | 72 |
| Qwen2.5-Coder-32B-Instruct | 开源模型 | API调用 | 32 |
| Qwen3-32B | 开源模型 | API调用 | 32 |
| GLM-4-32B-0414 | 开源模型 | API调用 | 32 |
| Qwen2.5-14B-HandPick | 微调模型 | API调用 | 14 |
Tab. 3 Information of candidate models
| 模型 | 模型类别 | 调用方式 | 参数量/109 |
|---|---|---|---|
| GPT-4o | 闭源模型 | API调用 | — |
| Gemini-1.5-pro | 闭源模型 | API调用 | — |
| Claude-3.5-Sonnet | 闭源模型 | API调用 | — |
| Qwen2.5-14B-Instruct | 开源模型 | API调用 | 14 |
| Qwen2.5-14B-CodeXGLUE | 微调模型 | API调用 | 14 |
| Qwen2.5-14B-Draper VDISC | 微调模型 | API调用 | 14 |
| Qwen2.5-14B-ReposVul | 微调模型 | API调用 | 14 |
| DeepSeek-V3 | 开源模型 | API调用 | 671 |
| Qwen2.5-72B-Instruct | 开源模型 | API调用 | 72 |
| Qwen2.5-Coder-32B-Instruct | 开源模型 | API调用 | 32 |
| Qwen3-32B | 开源模型 | API调用 | 32 |
| GLM-4-32B-0414 | 开源模型 | API调用 | 32 |
| Qwen2.5-14B-HandPick | 微调模型 | API调用 | 14 |
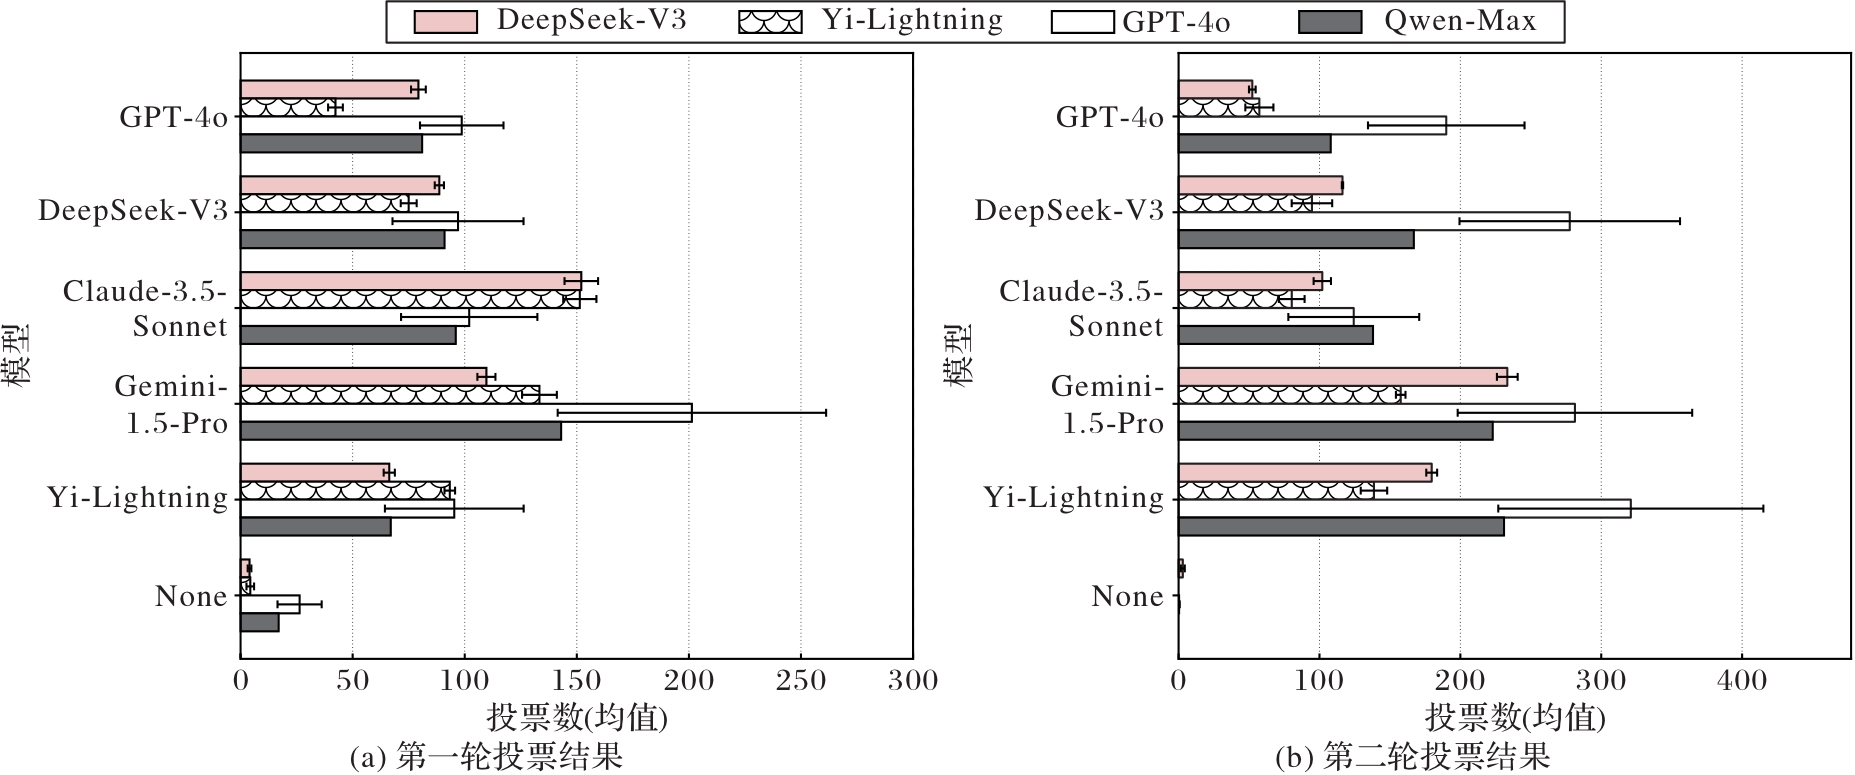
Fig. 4 Validation results of voting model on small-scale dataset
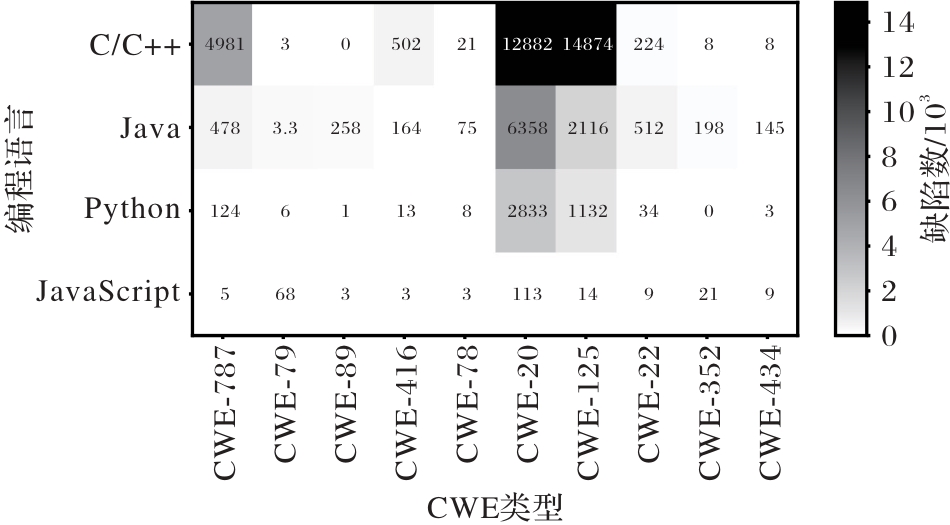
Fig. 5 Heatmap of CWE-TOP 10 distribution in different programming languages
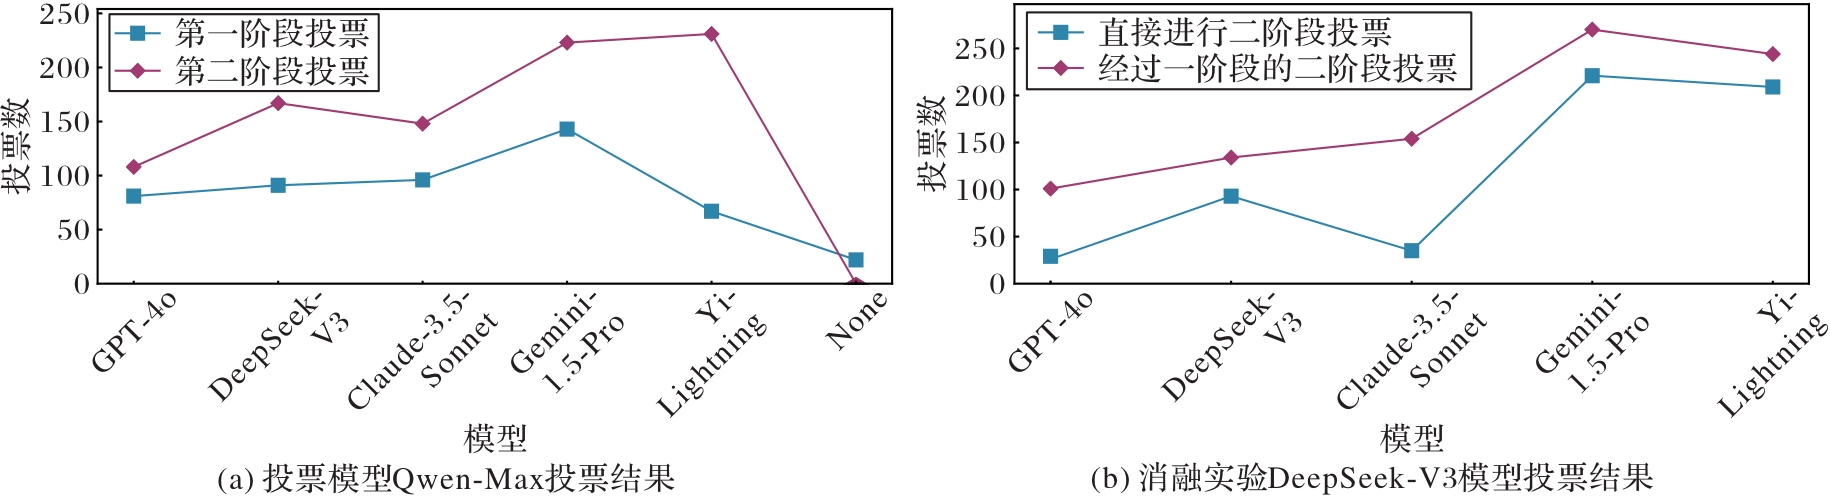
Fig. 6 Ablation experiment results
| 模型 | 精确率 | 召回率 | F1分数 | 准确率 |
|---|---|---|---|---|
| GPT-4o | 71.81 | 41.16 | 52.33 | 35.44 |
| Gemini-1.5-Pro | 59.00 | 23.23 | 33.33 | 20.00 |
| Claude-3.5-Sonnet | 78.32 | 58.78 | 67.16 | 50.55 |
| Qwen2.5-14B-Instruct | 50.88 | 16.72 | 25.17 | 14.40 |
| Qwen2.5-14B-CodeXGLUE* | 59.01 | 11.03 | 18.59 | 16.80 |
| Qwen2.5-14B-Draper VDISC* | 43.17 | 27.11 | 33.30 | 29.10 |
| Qwen2.5-14B-ReposVul* | 26.40 | 32.69 | 29.21 | 26.80 |
| DeepSeek-V3 | 60.91 | 24.94 | 35.39 | 21.50 |
| Qwen2.5-72B-Instruct | 70.02 | 37.85 | 49.14 | 41.00 |
| Qwen2.5-Coder-32B-Instruct | 63.45 | 11.37 | 19.29 | 25.30 |
| Qwen3-32B | 63.87 | 12.27 | 20.58 | 26.00 |
| GLM-4-32B-0414 | 55.27 | 53.53 | 54.39 | 46.50 |
| Qwen2.5-14B-HandPick* | 70.17 | 37.98 | 49.28 | 32.70 |
Tab. 4 Performance of various models on MegaVul test set
| 模型 | 精确率 | 召回率 | F1分数 | 准确率 |
|---|---|---|---|---|
| GPT-4o | 71.81 | 41.16 | 52.33 | 35.44 |
| Gemini-1.5-Pro | 59.00 | 23.23 | 33.33 | 20.00 |
| Claude-3.5-Sonnet | 78.32 | 58.78 | 67.16 | 50.55 |
| Qwen2.5-14B-Instruct | 50.88 | 16.72 | 25.17 | 14.40 |
| Qwen2.5-14B-CodeXGLUE* | 59.01 | 11.03 | 18.59 | 16.80 |
| Qwen2.5-14B-Draper VDISC* | 43.17 | 27.11 | 33.30 | 29.10 |
| Qwen2.5-14B-ReposVul* | 26.40 | 32.69 | 29.21 | 26.80 |
| DeepSeek-V3 | 60.91 | 24.94 | 35.39 | 21.50 |
| Qwen2.5-72B-Instruct | 70.02 | 37.85 | 49.14 | 41.00 |
| Qwen2.5-Coder-32B-Instruct | 63.45 | 11.37 | 19.29 | 25.30 |
| Qwen3-32B | 63.87 | 12.27 | 20.58 | 26.00 |
| GLM-4-32B-0414 | 55.27 | 53.53 | 54.39 | 46.50 |
| Qwen2.5-14B-HandPick* | 70.17 | 37.98 | 49.28 | 32.70 |
| [1] | Azam M, Nouman M, Gill A R. Comparative analysis of machine learning technique to improve software defect prediction: comparative analysis of machine learning technique to improve software defect prediction [J]. KIET Journal of Computing and Information Sciences, 2022, 5(2): 41-66. |
| [2] | Tan Z, Anagnostopoulos C, Singer J. OSPtrack: a labeled dataset targeting simulated execution of open-source software [C]// MSR 2025. Piscataway: IEEE, 2025: 659-663. |
| [3] | Mahbub P, Shuvo O, Rahman M M. Defectors: a large, diverse Python dataset for defect prediction [C]// MSR 2023. Piscataway: IEEE, 2023: 393-397. |
| [4] | Lu S, Guo D, Ren S, et al. CodeXGLUE: a machine learning benchmark dataset for code understanding and generation[PP/OL]. V2. arXiv (2021-03-16) [2025-08-22].. |
| [5] | Gezici Geçer B, Kolukısa Tarhan A. Explainable AI framework for software defect prediction [J]. Journal of Software: Evolution and Process, 2025, 37(4): No.e70018. |
| [6] | Wang J, Huang Y, Chen C, et al. Software testing with large language models: survey, landscape, and vision [J]. IEEE Transactions on Software Engineering, 2024, 50(4): 911-936. |
| [7] | Zhang Q, Fang C, Xie Y, et al. A survey on large language models for software engineering [J]. SCIENCE CHINA Information Sciences, 2026, 69(4): No.141102. |
| [8] | Zhang Z, Chen C, Liu B, et al. Unifying the perspectives of NLP and software engineering: a survey on language models for code [PP/OL]. V7. arXiv (2024-06-26) [2025-08-22].. |
| [9] | Borandag E. Software fault prediction using an RNN-based deep learning approach and ensemble machine learning techniques [J]. Applied Sciences, 2023, 13(3): No.1639. |
| [10] | Li Z, Li T, Wu Y, et al. Software defect prediction based on hybrid swarm intelligence and deep learning [J]. Computational Intelligence and Neuroscience, 2021, 2021: No.4997459. |
| [11] | Phuong H T M, Ngan D T K, Binh N T. A comparative study of deep learning techniques in software fault prediction [J]. The University of Danang - Journal of Science and Technology, 2024, 22(6B): 1-5. |
| [12] | Shin J, Aleithan R, Nam J, et al. Explainable software defect prediction: are we there yet? [PP/OL]. arXiv (2021-11-21) [2025-08-14].. |
| [13] | Nguyen D H, Seo A, Nnamdi N P, et al. False alarm reduction method for weakness static analysis using BERT model [J]. Applied Sciences, 2023, 13(6): No.3502. |
| [14] | Ashraf H, Alenezi M, Nadeem M, et al. Security assessment framework for educational ERP systems [J]. International Journal of Electrical and Computer Engineering, 2019, 9(6): 5570-5585. |
| [15] | Kim D, Jeon S, Kim K, et al. Guide to developing case-based attack scenarios and establishing defense strategies for cybersecurity exercise in ICS environment [J]. The Journal of Supercomputing, 2024, 80(15): 21642-21675. |
| [16] | Ouyang L, Wu J, Jiang X, et al. Training language models to follow instructions with human feedback [C]// NeurIPS 2022. Red Hook: Curran Associates Inc., 2022: 27730-27744. |
| [17] | Cheng Y, Shar L K, Zhang T, et al. LLM-enhanced static analysis for precise identification of vulnerable OSS versions [PP/OL]. arXiv (2024-08-14) [2025-06-21]. . |
| [18] | Fan L, Liu J, Liu Z, et al. Exploring the capabilities of LLMs for code change related tasks [J]. ACM Transactions on Software Engineering and Methodology, 2025, 34(6): No.159. |
| [19] | Hou X, Zhao Y, Liu Y, et al. Large language models for software engineering: a systematic literature review [J]. ACM Transactions on Software Engineering and Methodology, 2024, 33(8): No.220. |
| [20] | Kulsum U, Zhu H, Xu B, et al. A case study of LLM for automated vulnerability repair: assessing impact of reasoning and patch validation feedback [C]// AIware 2024. New York: ACM, 2024: 103-111. |
| [21] | Zhou X, Kim K, Xu B, et al. Out of sight, out of mind: better automatic vulnerability repair by broadening input ranges and sources [C]// CSE 2024. New York: ACM, 2024: 1071-1083. |
| [22] | Cheng Z, Wan D, Abueg M, et al. CI-Bench: benchmarking contextual integrity of AI assistants on synthetic data[PP/OL]. arXiv (2024-09-20) [2025-08-26].. |
| [23] | Elkins S, Kochmar E, Serban I, et al. How useful are educational questions generated by large language models? [C]// AIED 2023, CCIS 1831. Cham: Springer, 2023: 536-542. |
| [24] | He Z, Jiang H, Wang Z, et al. Position engineering: boosting large language models through positional information manipulation[C]// EMNLP 2024. Stroudsburg: ACL, 2024: 7333-7345. |
| [25] | Zamfirescu-Pereira J D, Wong R Y, Hartmann B, et al. Why Johnny can’t prompt: how non-AI experts try (and fail) to design LLM prompts [C]// CHI 2023. New York: ACM, 2023: No.431. |
| [26] | Wei J, Wang X, Schuurmans D, et al. Chain-of-thought prompting elicits reasoning in large language models[C]// NeurIPS 2022. Red Hook: Curran Associates Inc., 2022: 24824-24837. |
| [27] | Liu J, Xia C S, Wang Y, et al. Is your code generated by ChatGPT really correct? rigorous evaluation of large language models for code generation [C]// NeurIPS 2023. Red Hook: Curran Associates Inc., 2023: 21558-21572. |
| [28] | Haque M M A, Ahmad W U, Lourentzou I, et al. FixEval: execution-based evaluation of program fixes for programming problems[C]// APR 2023. Piscataway: IEEE, 2023: 11-18. |
| [29] | Huq F, Hasan M, Haque M M A, et al. Review4Repair: code review aided automatic program repairing [J]. Information and Software Technology, 2022, 143: No.106765. |
| [30] | Tufano M, Watson C, Bavota G, et al. An empirical investigation into learning bug-fixing patches in the wild via neural machine translation [C]// ASE 2018. New York: ACM, 2018: 832-837. |
| [31] | Khan M A M, Bari M S, Do X L, et al. xCodeEval: a large scale multilingual multitask benchmark for code understanding, generation, translation and retrieval [C]// ACL 2024 (Volume 1: Long Papers). Stroudsburg: ACL, 2024: 6766-6805. |
| [32] | Csuvik V, Vidács L. FixJS: a dataset of bug-fixing JavaScript commits [C]// MSR 2022. New York: ACM, 2022: 712-716. |
| [33] | Common Weakness Enumeration. CWE top 25 most dangerous software weaknesses — 2023[R/OL]. [2025-08-15].. |
| [34] | Gu J, Jiang X, Shi Z, et al. A survey on LLM-as-a-judge [PP/OL]. V3. arXiv (2025-01-09) [2025-07-13]. . |
| [35] | SUROWIEKI J. The wisdom of crowds: why the many are smarter than the few and how collective wisdom shapes business, economies, societies, and nations [M]. New York: Doubleday, 2004: 63-65. |
| [36] | Aggarwal C C. Outlier analysis [M]. 2nd ed. Cham: Springer, 2017: 1-34. |
| [37] | Hawkins D M. Identification of outliers, MSAP[M]. Dordrecht: Springer, 1980:1-12. |
| [38] | Ni C, Shen L, Yang X, et al. MegaVul: AC/C++ vulnerability dataset with comprehensive code representations[C]// MSR 2024. New York: ACM, 2024: 738-742. |
| [39] | Chen J, Xiao S, Zhang P, et al. BGE M3-Embedding: multi-lingual, multi-functionality, multi-granularity text embeddings through self-knowledge distillation [C]// Findings of the Association for Computational Linguistics: ACL 2024. Stroudsburg: ACL, 2024: 2318-2335. |
| [40] | Russell R, Kim L, Hamilton L, et al. Automated vulnerability detection in source code using deep representation learning [C]// ICMLA 2018. Piscataway: IEEE, 2018: 757-762. |
| [41] | Wang X, Hu R, Gao C, et al. ReposVul: a repository-level high-quality vulnerability dataset[C]// ICSE-Companion 2024. New York: ACM, 2024: 472-483. |
| [1] | Mengjiao YU, Min JIN, Xinhua LIU. Agile enhancement development framework driven by human-multi-agent collaboration [J]. Journal of Computer Applications, 2026, 46(9): 2938-2947. |
| [2] | Zhenhui GONG, Xiaoyu SHI, Yun LU, Yangcheng LIU, Mingsheng SHANG. Fair recommendation framework for large language models with sensitive attribute absence [J]. Journal of Computer Applications, 2026, 46(9): 2838-2846. |
| [3] | Yaoran HUO, Huizhi LI, Dahe ZENG, Zhenyu TANG, Chenmei LIU, Yan WU, Xiao ZHANG, Siqin CHEN, Houhui YANG. Contract review framework based on dynamic rule generation and neuro-symbolic reasoning using large language models [J]. Journal of Computer Applications, 2026, 46(9): 2820-2826. |
| [4] | Xinliang LIU, Yushi XU, Dubai LI, Yanzhao REN. Survey of knowledge graph-based question answering methods [J]. Journal of Computer Applications, 2026, 46(8): 2394-2410. |
| [5] | Yue ZHANG, Yuhan GUO. Ride-hailing spatio-temporal demand forecasting method via large language model-driven semantic quantification [J]. Journal of Computer Applications, 2026, 46(8): 2467-2476. |
| [6] | Mengting WANG, Shuanliang GAO, Wenrui LIAO, Geng LI, Jiaxing ZHANG, Yuanfang ZHU, Tiange ZHAO, Yonghui LIU, Hongru LIANG. Message consistency parsing framework for aviation domain [J]. Journal of Computer Applications, 2026, 46(8): 2681-2690. |
| [7] | Yadian CHENG, Yingying LI, Ping ZHANG, Fangbing QIU, Xiaonan CHAI, Yuqiao SHU. Dual-role interaction mechanism-based large language model for psychological health [J]. Journal of Computer Applications, 2026, 46(7): 2054-2063. |
| [8] | Linkai ZHU, Lu YANG, Hongjie ZHANG, Zijin WU, Lu LIU. Smart contract generation framework driven by LLM and SWRL for cross-border data compliance across heterogeneous blockchains [J]. Journal of Computer Applications, 2026, 46(7): 2074-2084. |
| [9] | Jiahang LI, Qilong HAN, Lijie LI, Hui ZHANG. Large language model-driven method for qualifier enhancement in hyper-relational knowledge graphs [J]. Journal of Computer Applications, 2026, 46(7): 2043-2053. |
| [10] | Didi HOU, Shaodong HONG, Yujie FU, Yunhe CUI, Guowei SHEN. Cybersecurity named entity recognition method based on large language model linking [J]. Journal of Computer Applications, 2026, 46(7): 2064-2073. |
| [11] | Yuqi WANG, Yangsen ZHANG, Pu WANG. High school English reading comprehension model integrating knowledge augmentation and contrastive learning [J]. Journal of Computer Applications, 2026, 46(7): 2096-2103. |
| [12] | Miaogen LING, Rui JING, Wei FANG. Survey of research on applications of explainable deep learning in tropical cyclone forecasting [J]. Journal of Computer Applications, 2026, 46(7): 2318-2326. |
| [13] | Yusheng YI, Zhaohao HUANG, Zihao DENG, Leilei KONG, Haoliang QI. CORER: collaborative multi-knowledge large language model prompt framework for IT application innovation database migration [J]. Journal of Computer Applications, 2026, 46(6): 1811-1817. |
| [14] | Taixin CAI, Fengfeng WEI. Large language model-enhanced ant colony optimization for multi-solution traveling salesman problems [J]. Journal of Computer Applications, 2026, 46(6): 1712-1720. |
| [15] | Jintao WANG, Zhilin GAO, Qixiang MENG, Fanliang BU. Legal case retrieval method via case information reformulation using large language model [J]. Journal of Computer Applications, 2026, 46(6): 1785-1792. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||
